This repository hosts the GGUF (llama.cpp) quantized version of MiniCPM-V 4.6. For the original BF16 weights and the full model card, please refer to openbmb/MiniCPM-V-4.6.
A Pocket-Sized MLLM for Ultra-Efficient Image and Video Understanding on Your Phone
GitHub | MiniCPM Wiki(Chinese) | CookBook | Demo |
Feishu (Lark)
News
- [2026.05.17] ⭐️⭐️⭐️ We release the API service of MiniCPM-V 4.6, with a public free API key together! Try it now.
MiniCPM-V 4.6
MiniCPM-V 4.6 is our most edge-deployment-friendly model to date. The model is built based on SigLIP2-400M and the Qwen3.5-0.8B LLM. It inherits the strong single-image, multi-image, and video understanding capabilities of MiniCPM-V family, while significantly improving computation efficiency. It also introduces mixed 4x/16x visual token compression. Notable features of MiniCPM-V 4.6 include:
-
🔥 Leading Foundation Capability.
MiniCPM-V 4.6 scores 13 on the Artificial Analysis Intelligence Index benchmark, outperforming Qwen3.5-0.8B's score of 10 with 19x fewer token cost, and Qwen3.5-0.8B-Thinking's score of 11 with 43x fewer token cost. It also surpasses the larger Ministral 3 3B (score of 11).
-
💪 Strong Multimodal Capability.
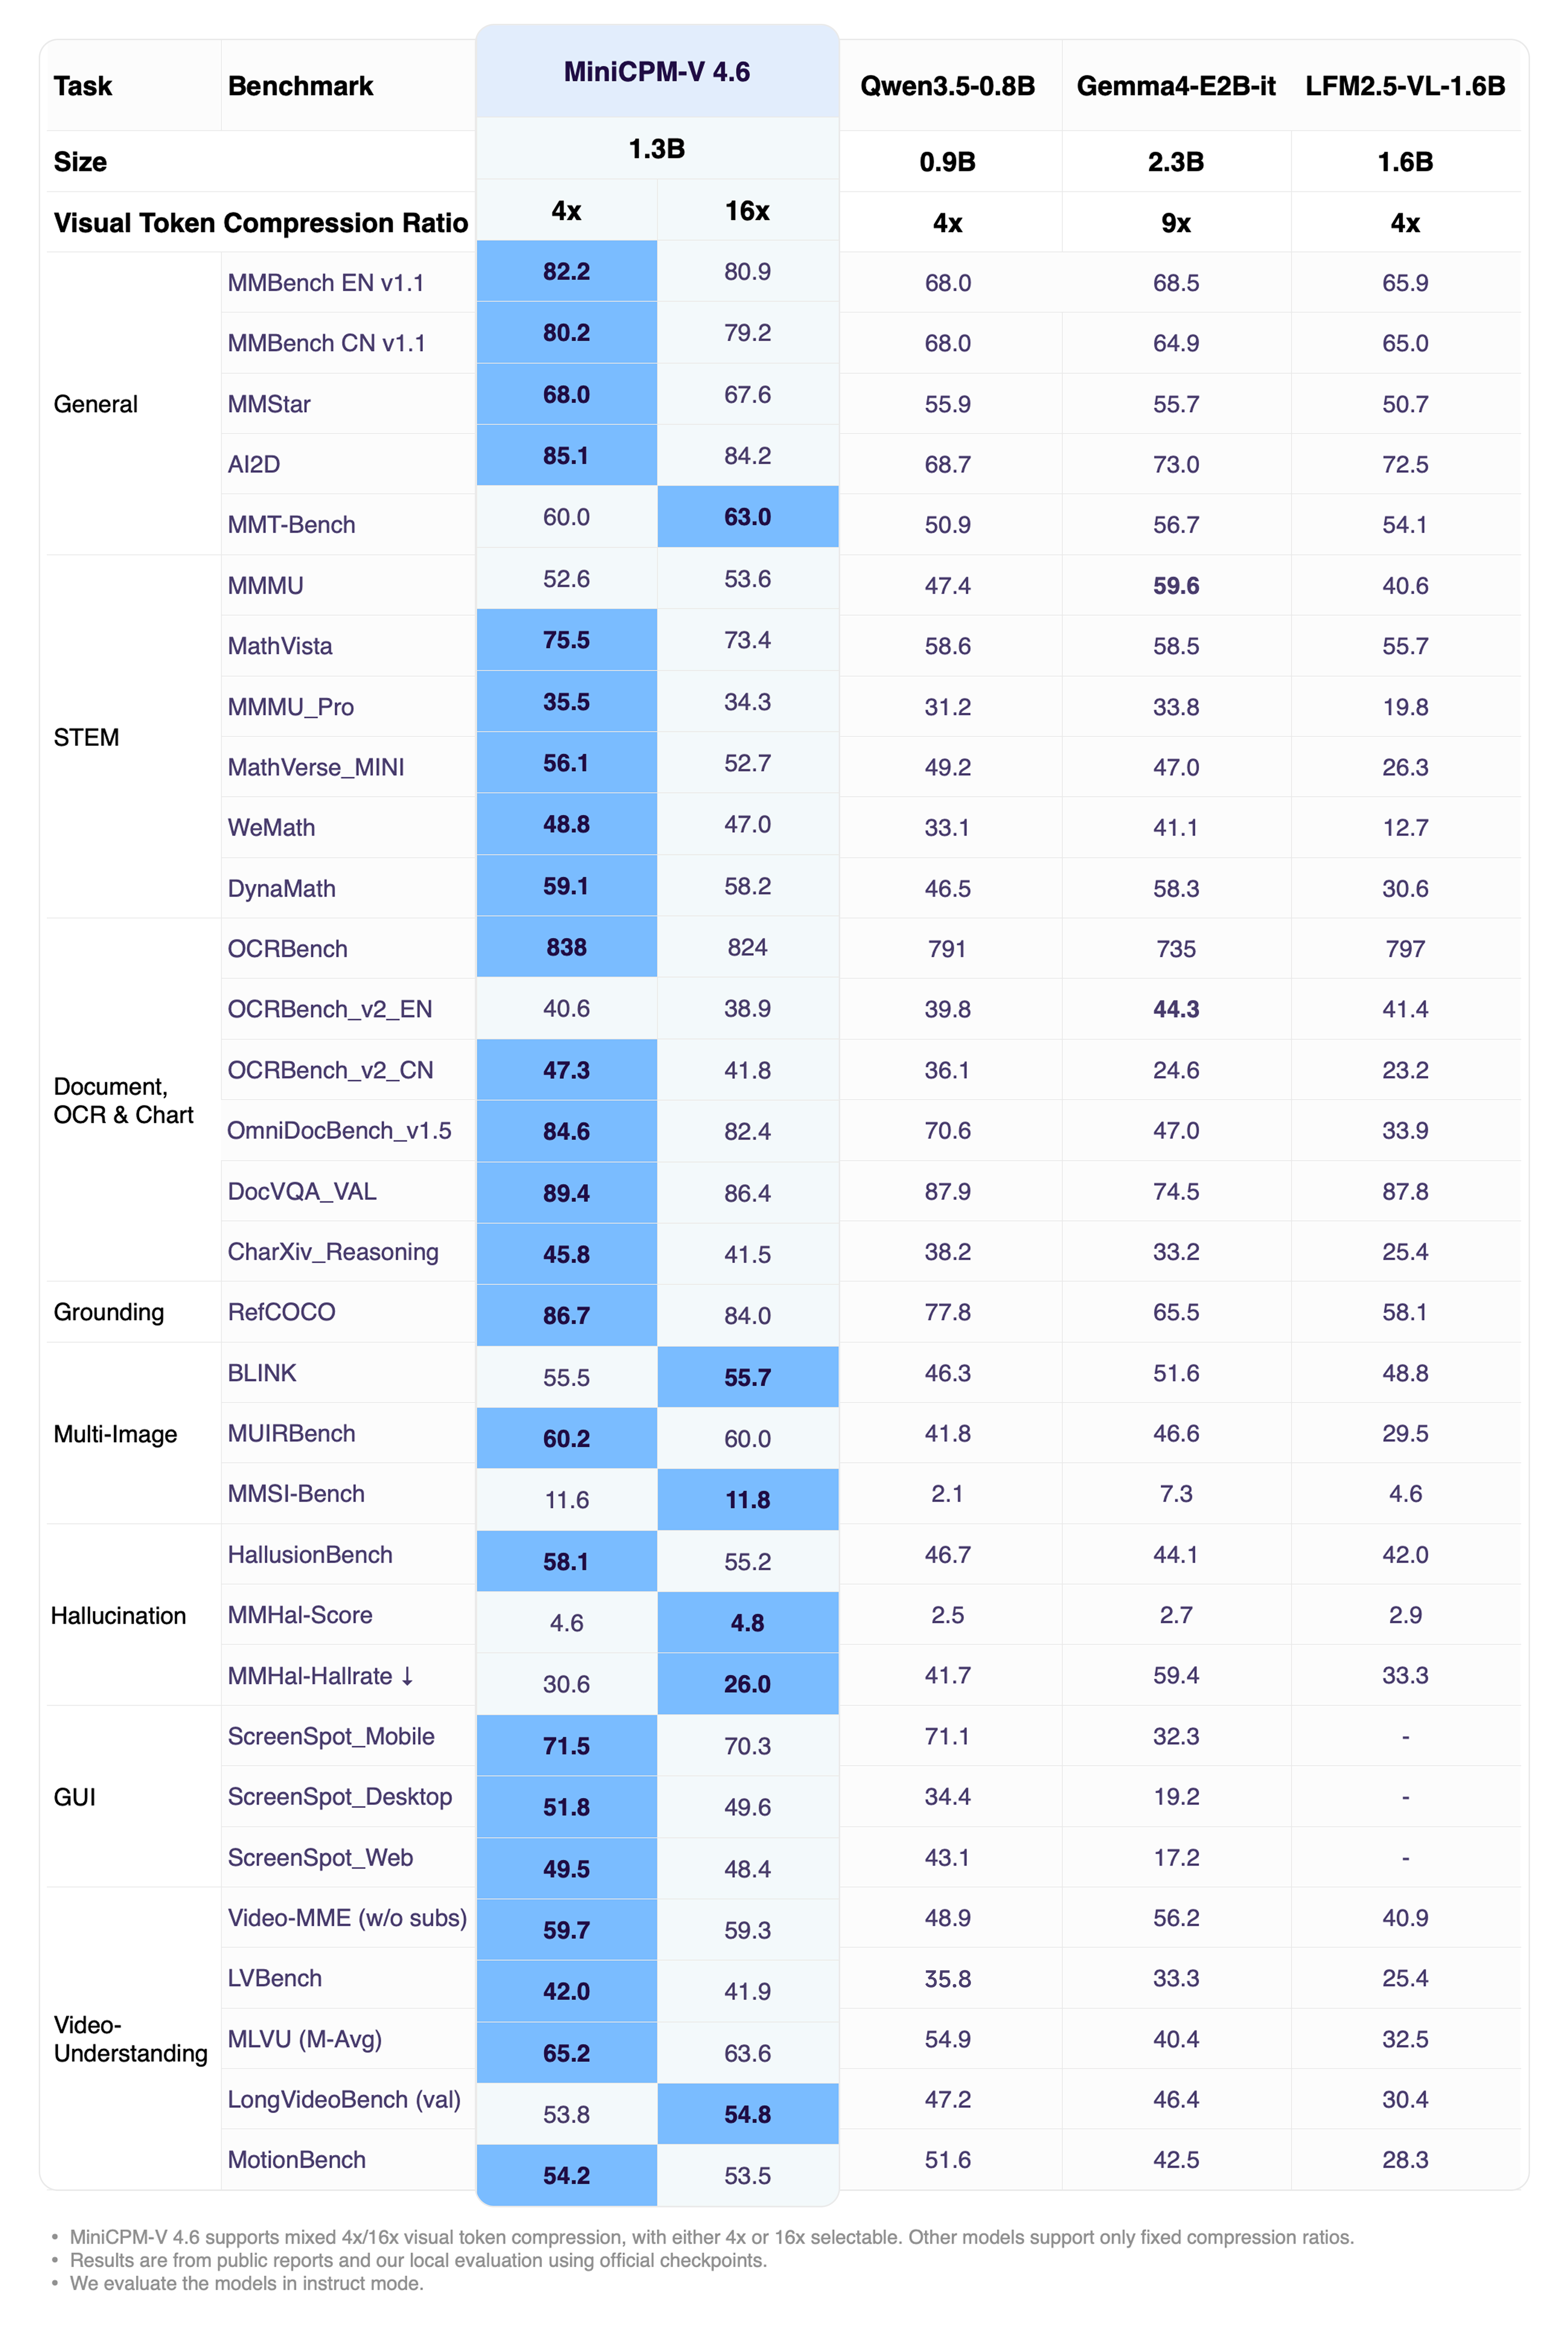
MiniCPM-V 4.6 outperforms Qwen3.5-0.8B on most vision-language understanding tasks, and reaches Qwen3.5 2B-level capability on many benchmarks including OpenCompass, RefCOCO, HallusionBench, MUIRBench, and OCRBench.
-
🚀 Ultra-Efficient Architecture.
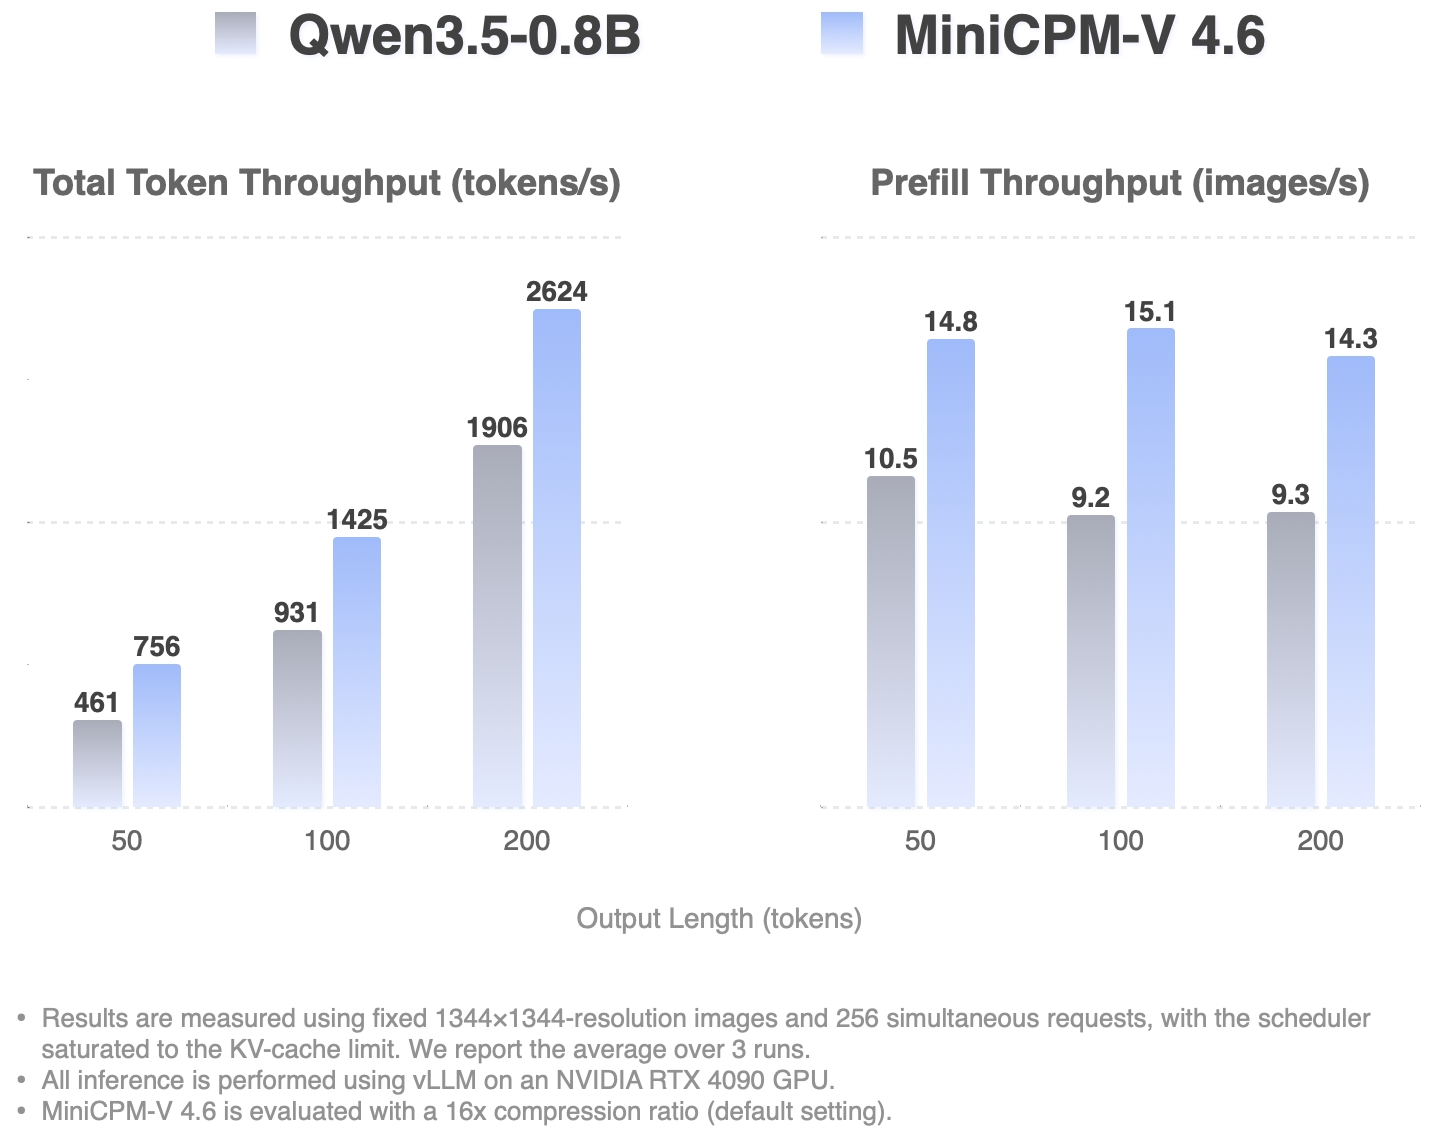
Based on the latest technique in LLaVA-UHD v4, MiniCPM-V 4.6 reduces the visual encoding computation FLOPs by more than 50%. It enables MiniCPM-V 4.6 to achieve better efficiency to even smaller models, achieving ~1.5x token throughput compared to Qwen3.5-0.8B.
It also supports mixed 4x/16x visual token compression rate, allowing flexible switching between accuracy and speed.
-
📱 Broad Mobile Platform Coverage.
MiniCPM-V 4.6 can be deployed across all three mainstream mobile platforms — iOS, Android, and HarmonyOS. With every edge adaptation code open-sourced, developers can reproduce the on-device experience in just a few steps.
-
🛠️ Developer Friendly.
MiniCPM-V 4.6 is adapted to inference frameworks such as vLLM, SGLang, llama.cpp, Ollama, and supports fine-tuning ecosystems such as SWIFT and LLaMA-Factory. Developers can quickly customize models for new domains and tasks on consumer-grade GPUs. We provide multiple quantized variants across GGUF, BNB, AWQ, and GPTQ formats.
Evaluation
Overall Performance (Instruct)
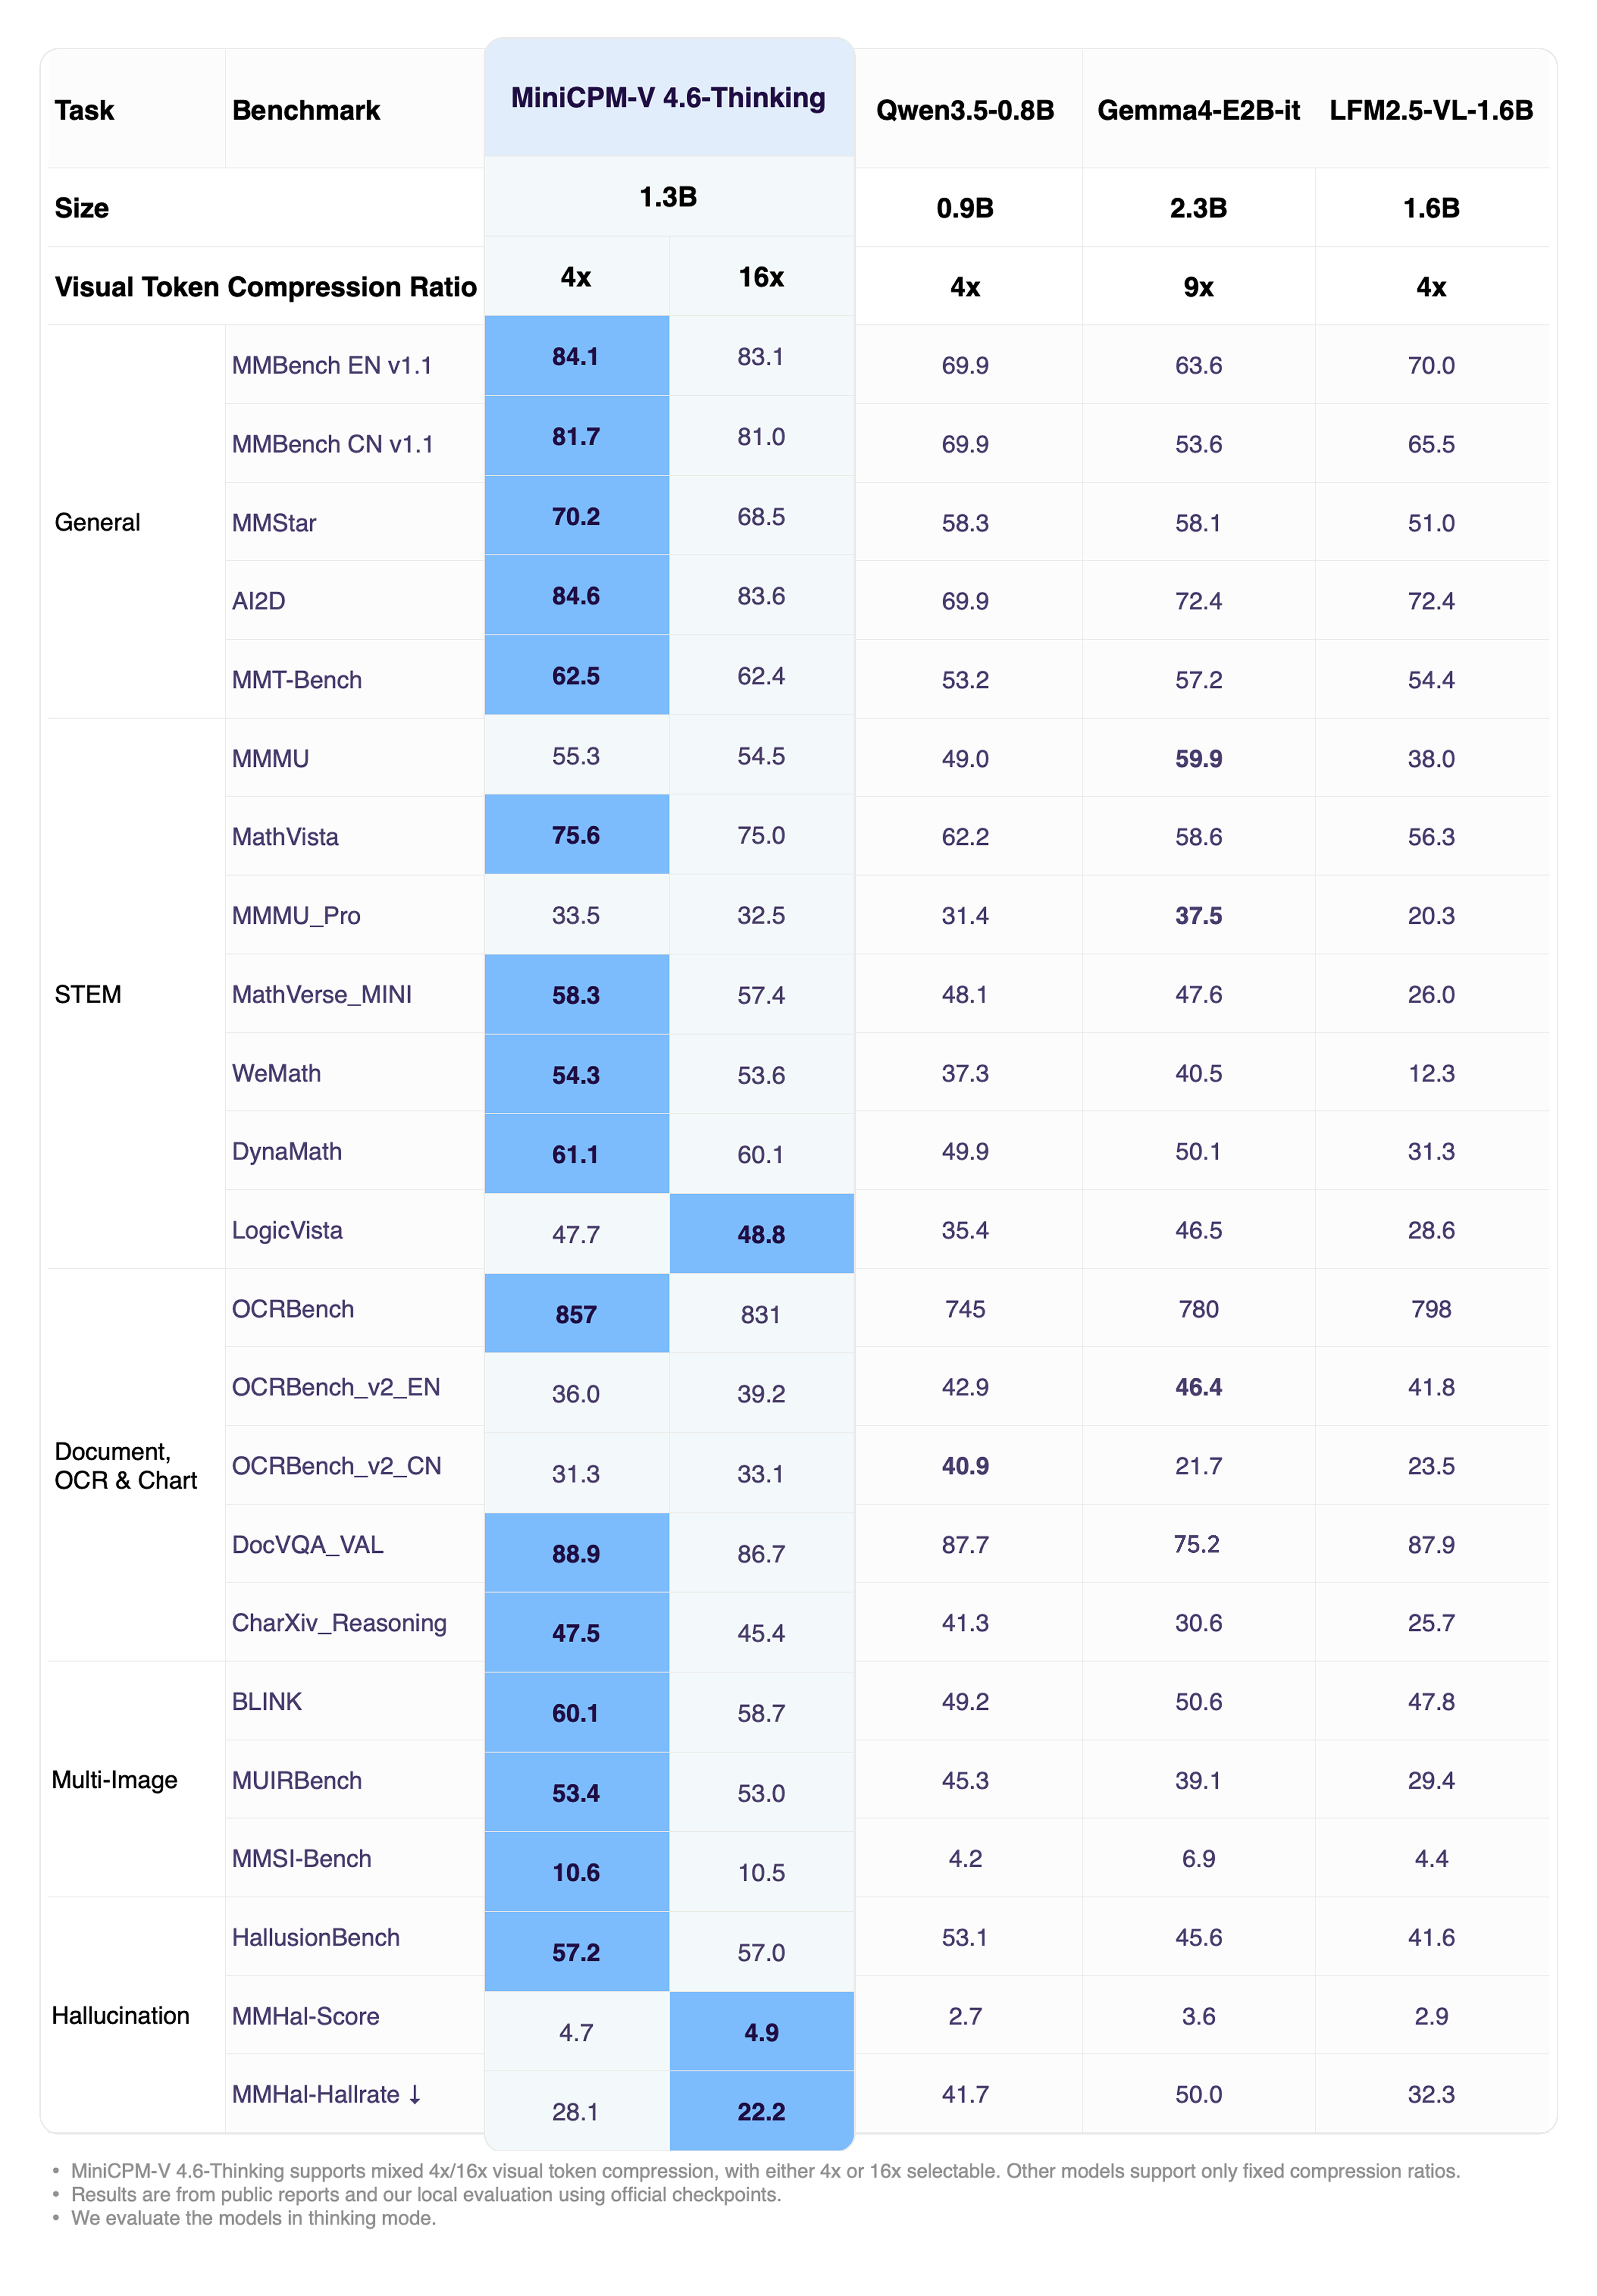
Click to view MiniCPM-V 4.6-Thinking performance.
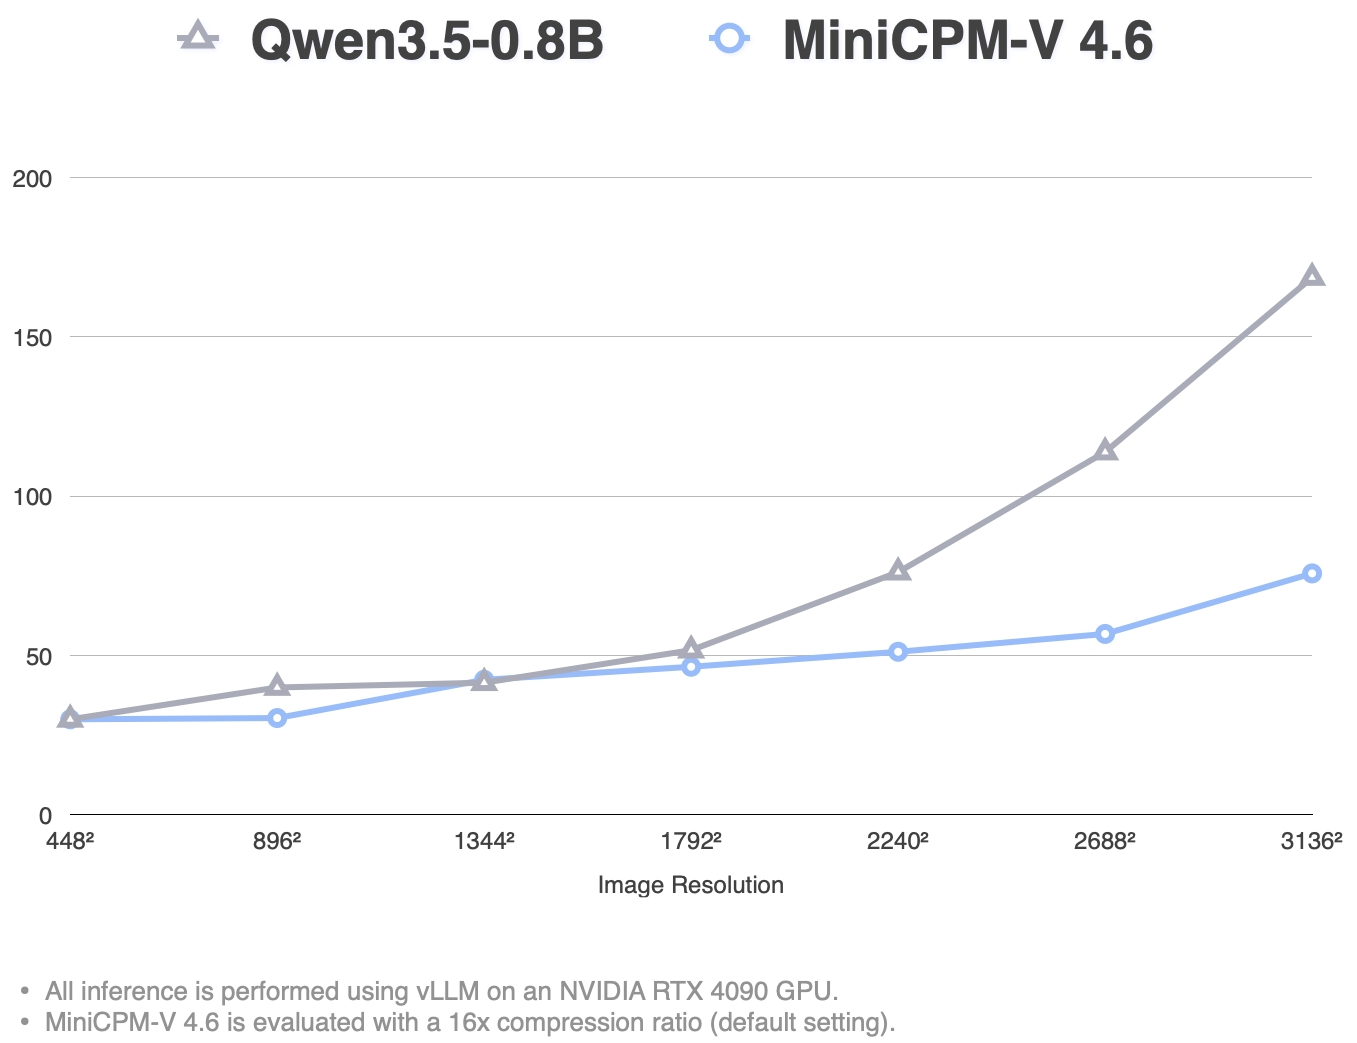
Click to view MiniCPM-V 4.6 inference efficiency results.
High-Concurrency Throughput
Single Request TTFT (ms)
Examples
Overall
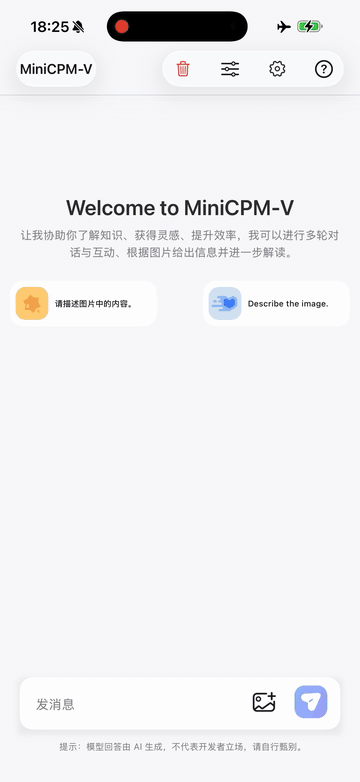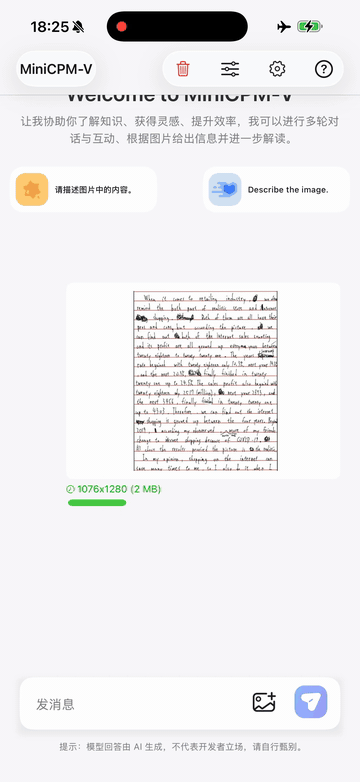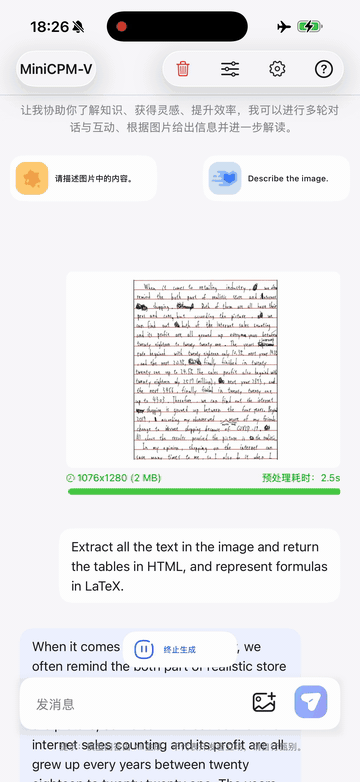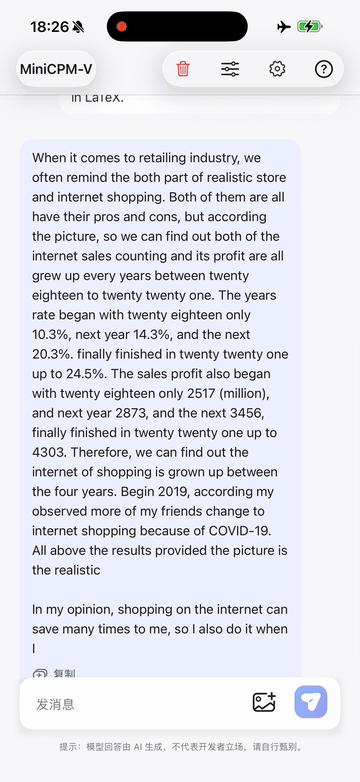
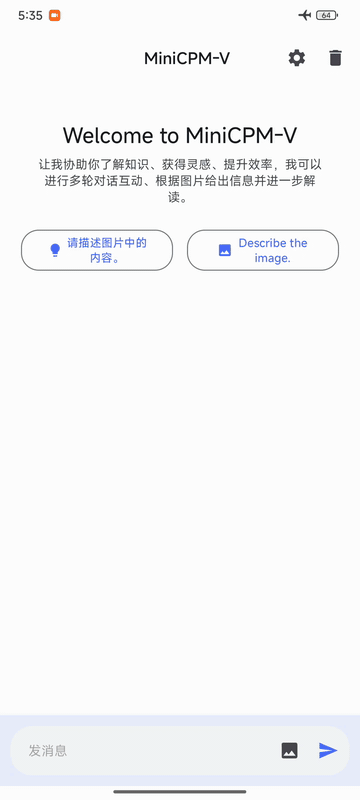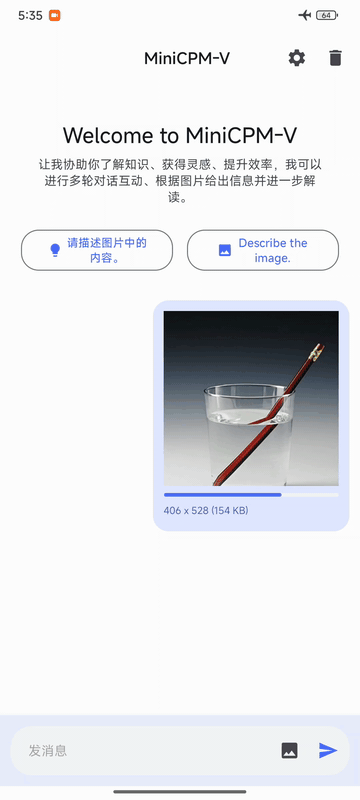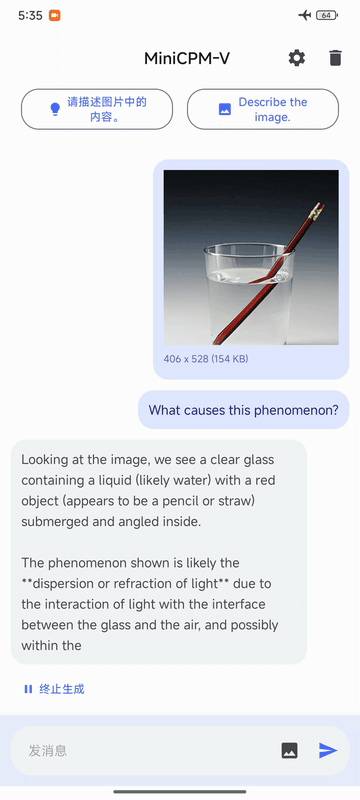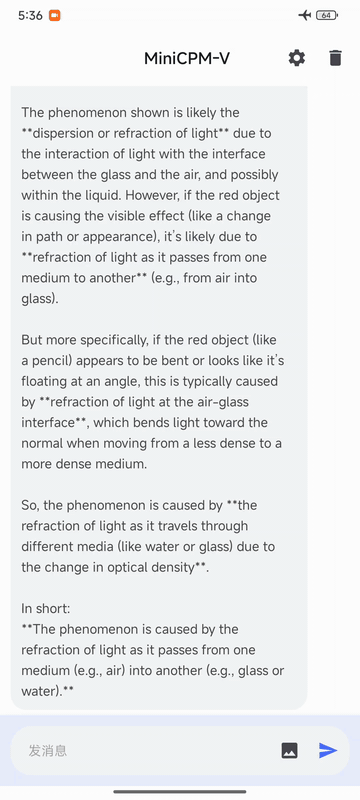
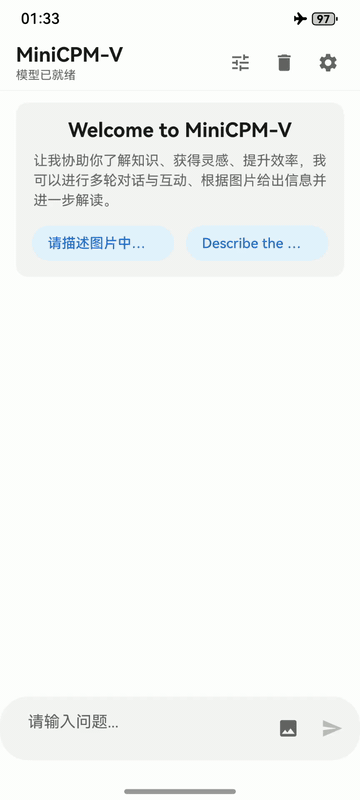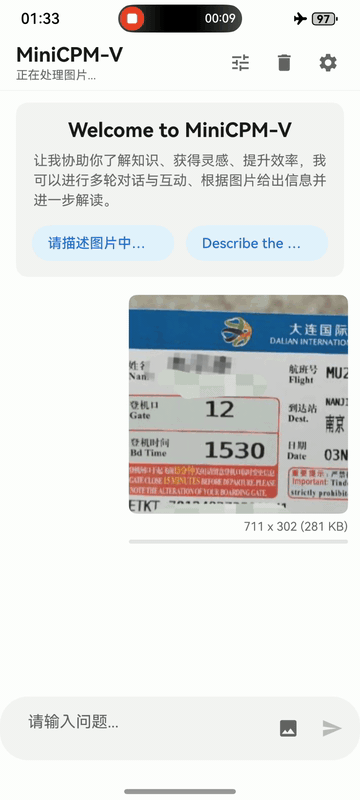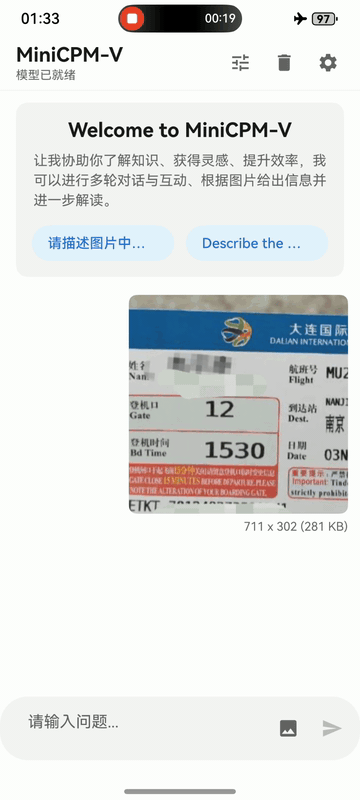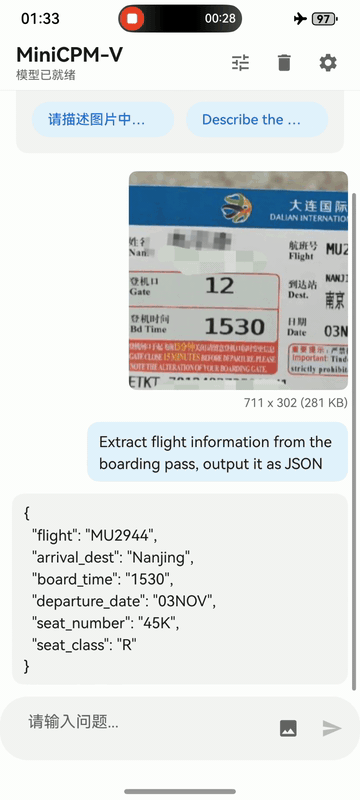
MiniCPM-V 4.6 can be deployed across three mainstream end-side platforms — iOS, Android and HarmonyOS. The clips below are raw screen recordings on phone devices without edition.
Usages
Inference with Transformers
Installation
Note on CUDA compatibility: torchcodec (used for video decoding) may have compatibility issues with certain CUDA versions. For example, torch>=2.11 bundles CUDA 13.1 by default, while environments with CUDA 12.x may encounter errors such as RuntimeError: Could not load libtorchcodec. Two workarounds:
- Replace
torchcodec with PyAV — supports both image and video inference without CUDA version constraints:
- Pin the CUDA version when installing torch to match your environment (e.g. CUDA 12.8):
Load Model
Image Inference
Video Inference
Advanced Parameters
You can customize image/video processing by passing additional parameters to apply_chat_template:
Note: downsample_mode must be passed to both apply_chat_template (for correct placeholder count) and generate (for the vision encoder). All other parameters only need to be passed to apply_chat_template.
Serving with transformers serve
Hugging Face Transformers includes a lightweight OpenAI-compatible server for quick testing and moderate-load deployment.
Start the server:
Send a request:
Tool calling example:
The model returns a natural-language explanation followed by a structured <tool_call> block embedded in the content field. Note that a dedicated tool call parser for this format has not yet been added to the transformers library, so the tool calls need to be extracted manually via regex for now.
Handling Escaped Newlines in Model Outputs
In some cases, the model might output escaped newline characters \n as string literals instead of actual newlines. To render the text correctly, especially in UI layers, you can use the following utility function. This function carefully replaces literal \n with real newlines while protecting scenarios where \n has specific semantic meaning.
Utility Function:
Deploy MiniCPM-V 4.6 on iOS, Android, and HarmonyOS Platforms
We have adapted MiniCPM-V 4.6 for deployment on iOS, Android, and HarmonyOS platforms, with all edge adaptation code fully open-sourced. Developers can reproduce the on-device experience in just a few steps. Visit our edge deployment repository for platform-specific build guides, or go to the download page to try pre-built apps directly.
[blocked]
Use MiniCPM-V 4.6 in Other Inference and Training Frameworks
MiniCPM-V 4.6 supports multiple inference and training frameworks. Below are quick-start commands for each. For full details, see our Cookbook.
vLLM — Full Guide
Note: --enable-auto-tool-choice and --tool-call-parser qwen3_coder enable tool/function calling support. If you don't need tool use, you can omit these flags and simply run vllm serve openbmb/MiniCPM-V-4.6.
Tool calling example:
SGLang — Full Guide
llama.cpp — Full Guide
Ollama — Full Guide
In the interactive session, paste an image path or URL directly to chat with the model.
LLaMA-Factory (Fine-tuning) — Full Guide
ms-swift (Fine-tuning) — Full Guide
License
Model License
- The MiniCPM-o/V model weights and code are open-sourced under the Apache-2.0 license.
Statement
- As MLLMs, MiniCPM-o/V models generate content by learning a large number of multimodal corpora, but they cannot comprehend, express personal opinions, or make value judgements. Anything generated by MiniCPM-o/V models does not represent the views and positions of the model developers
- We will not be liable for any problems arising from the use of MiniCPM-o/V models, including but not limited to data security issues, risk of public opinion, or any risks and problems arising from the misdirection, misuse, dissemination, or misuse of the model.
Technical Reports and Key Techniques Papers
👏 Welcome to explore key techniques of MiniCPM-o/V and other multimodal projects of our team:
Technical Reports: MiniCPM-o 4.5 | MiniCPM-V 4.5 | MiniCPM-o 2.6 | MiniCPM-Llama3-V 2.5 | MiniCPM-V 2.0
Other Multimodal Projects: VisCPM | RLPR | RLHF-V | LLaVA-UHD | RLAIF-V | LLaVA-UHD-v4
Citation
If you find our model/code/paper helpful, please consider citing our papers 📝 and staring us ⭐️!